
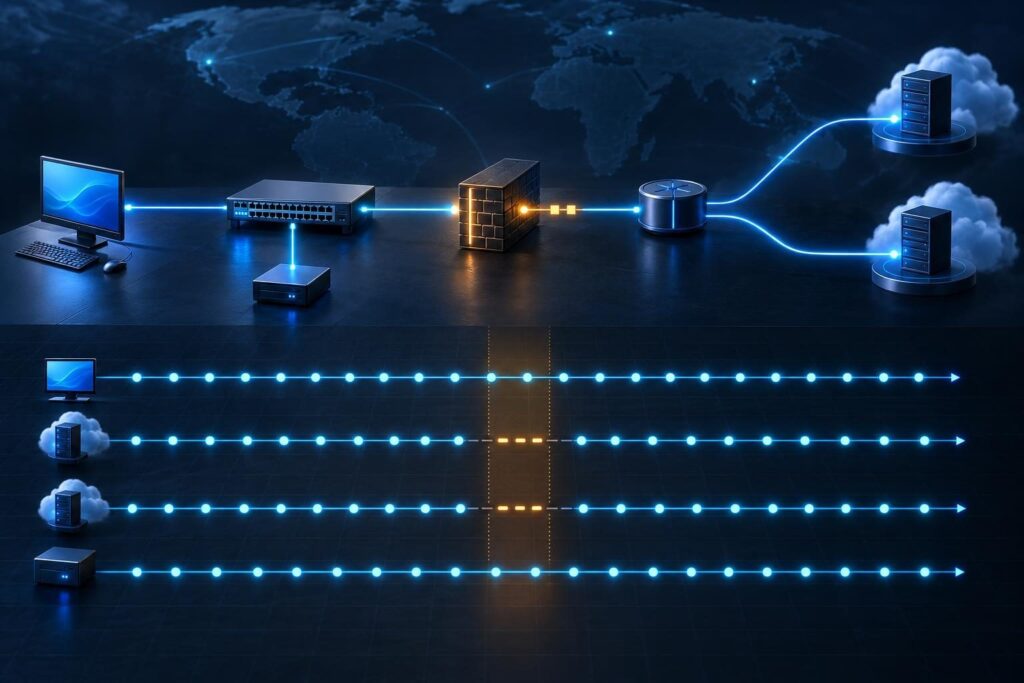
A packet loss timeline helps explain network failures that disappear before anyone can investigate. A single speed test or short ping session rarely catches these events. Instead, collect simultaneous measurements across the suspected path. Match missing replies with application symptoms, interface errors, and traffic levels.
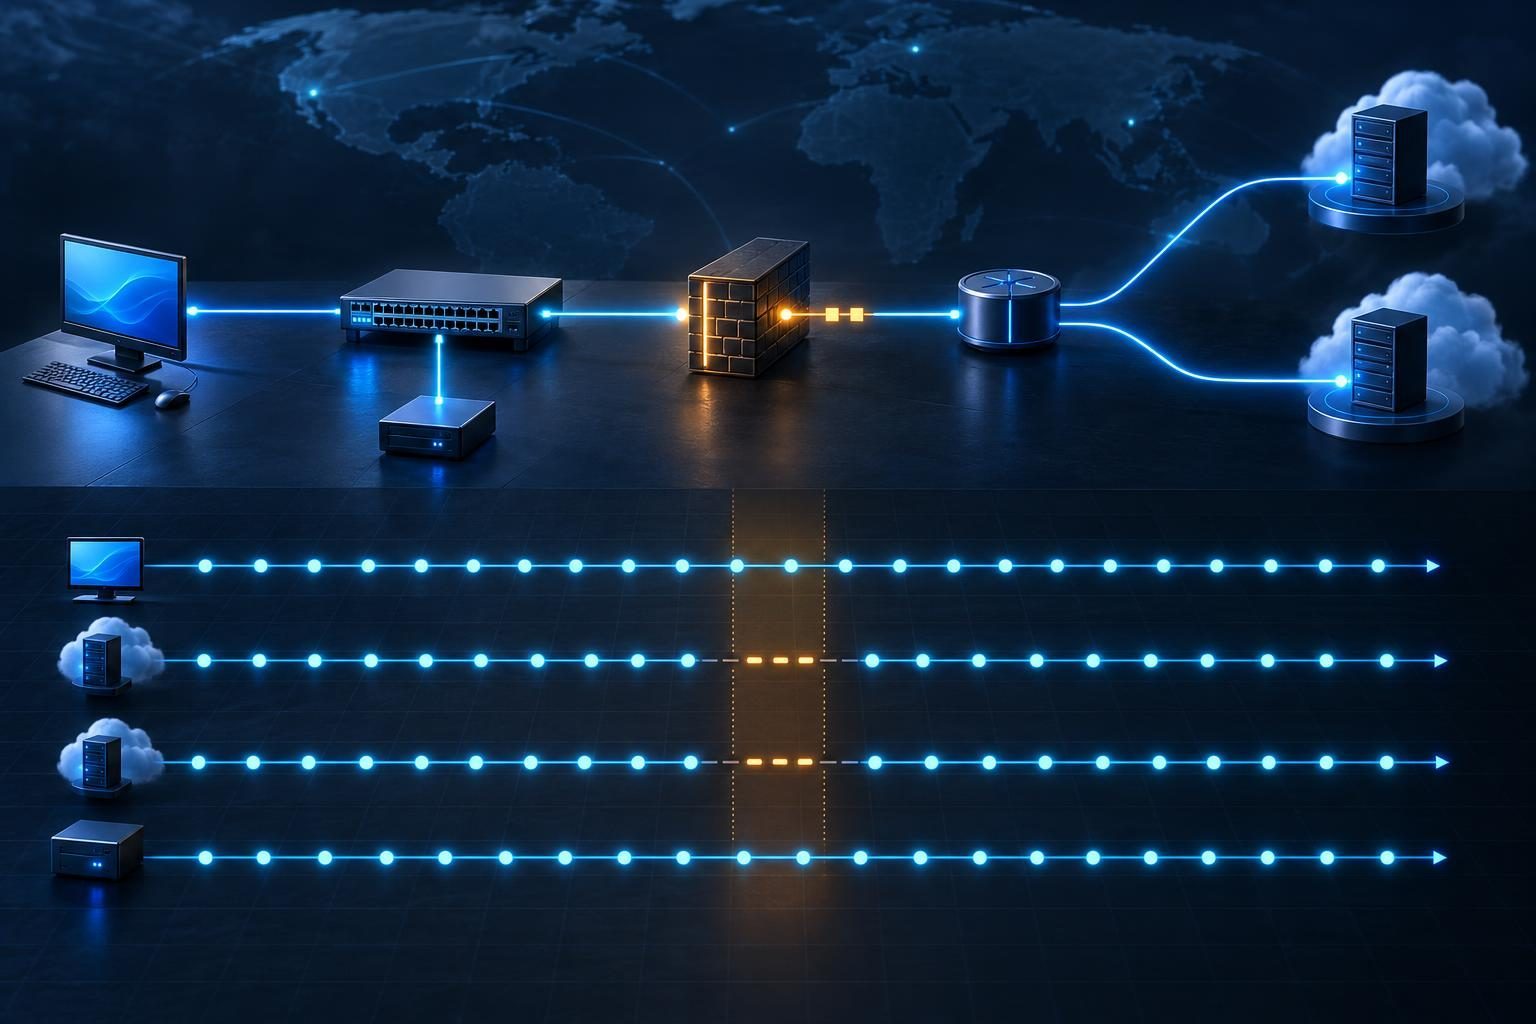
This guide focuses on capturing brief loss bursts and preparing useful escalation evidence. The goal is not simply to prove that packets disappear. You need to identify which network segment deserves investigation, while avoiding misleading results from intermediate routers.
Define the Event Before Starting Continuous Tests
Packet loss means traffic fails to reach its destination. However, a missing ping reply does not prove that an application packet disappeared. The destination might ignore probes, or the reply might encounter trouble on its return journey.
First, record the symptom in plain language. Does a call break up, a remote desktop freeze, or a file transfer pause? Note the affected device, network connection, service, and exact time.
- Record the time zone and check clock synchronization on test devices.
- Identify whether one user, one floor, or the entire site experiences trouble.
- Note recurring triggers, such as backups, camera uploads, or shift changes.
- List recent changes without assuming they caused the failure.
Choose an observation window that includes both normal operation and the suspected failure period. A clean five-minute sample cannot clear a network that fails once each afternoon.
Keep investigation steps separate from corrective changes. Google’s evidence-based troubleshooting guidance explains why testing specific hypotheses works better than changing several settings together.
Build a Packet Loss Timeline With Parallel Probes
Run low-rate, timestamped probes from the affected computer to several targets at the same time. Start around one probe per second, subject to local policy and target permission. Avoid flood modes and large-scale probing.
- Local peer: A reliable wired device on the same network segment.
- Default gateway: The router that carries traffic beyond the local network.
- External target: An approved, stable endpoint known to answer probes.
- Affected service: Its endpoint, when its operator allows testing.
Use numeric addresses initially to separate path testing from name resolution. Keep the address family consistent: IPv4 and IPv6 can follow different paths. Record whether a VPN carries each probe.
Measure round-trip time, or RTT, alongside missing replies. RTT includes the outward and return journeys. Save individual samples rather than only averages. Brief latency spikes and consecutive losses can disappear inside an hourly summary.
For each target, retain timestamps, probe intervals, sent counts, missing counts, and the longest burst of missing replies. Use a logging tool that records time per sample. Ordinary ping output does not always provide timestamps.
Establish a Latency Baseline Without Hiding Short Bursts
Collect a quiet-period baseline before interpreting busy-period results. Record typical RTT, maximum RTT, and variation between samples. Then repeat the same measurements during normal business activity.
A rising RTT followed by missing replies can suggest queue pressure. Network queues hold packets while an interface waits to send them. That pattern supports a congestion hypothesis, but it does not prove congestion alone caused the event.
Probe frequency limits what you can detect. One probe each second may miss a shorter interruption. Application logs and interface counters can fill that gap without increasing probe traffic aggressively.
When ping remains clean, check the affected service directly. An approved connection test to its actual service port may reveal failures that ping misses. Keep those tests modest and avoid repeated logins or expensive application requests.
For voice symptoms, compare network timing with call statistics. Our guide to delayed audio and jitter explains why conversation quality needs more than an average latency figure.
Use Hop-by-Hop Tests Without Blaming the Wrong Router
A hop is a router along a network path. Traceroute identifies responding hops by sending probes with limited lifetimes. Tools such as MTR combine repeated path discovery with response statistics.
Capture a path trace during healthy operation and another during the failure. Windows provides tracert; Linux commonly offers traceroute or mtr, depending on installed packages. Confirm tool options before use.
Interpret the results carefully:
- One intermediate hop misses replies, but later hops stay clean: This often reflects limited probe responses, not forwarding loss.
- Loss begins at one hop and continues through the destination: Investigate that region, but confirm with independent evidence.
- Every external target fails while local probes remain clean: Focus on the gateway’s outward path and shared upstream dependencies.
- Only one destination fails: Compare its route and service health before blaming the whole connection.
Routers may give diagnostic replies lower priority than forwarded traffic. Return paths can also differ from outward paths. Load balancing can produce different hop sequences between probes. Therefore, a trace narrows the investigation; it rarely identifies a faulty interface by itself.
Run Wired Isolation Tests During the Same Failure Window
Repeat the probes over Ethernet using a known-good cable and suitable switch port. Verify that the test computer actually uses Ethernet. Disable Wi-Fi only when doing so will not remove your support connection.
Keep the destination, timing, VPN state, and workload as consistent as possible. A wired test after the outage ends provides weak evidence about wireless behavior during the outage.
Where possible, run a second wired computer in parallel. If both devices show matching bursts, a shared path becomes more likely. If only one fails, investigate its adapter, dock, software, cable, and port.
A clean wired comparison directs the next step toward wireless performance isolation. It does not automatically prove weak signal caused the problem.
Do not bypass the firewall by connecting a business computer directly to an internet handoff. Such tests require explicit authorization, endpoint protection, and a recovery plan.
Correlate Interface Errors and Congestion With Loss
Take interface-counter snapshots before and after the event. Check the endpoint, its switch port, switch uplinks, and the gateway’s internet-facing interface. Preserve existing counters rather than clearing them immediately.
Useful indicators include:
- CRC or frame errors: These count damaged Ethernet frames and suggest a physical-link investigation.
- Discards or queue drops: These may reflect congestion, policy, or exhausted resources.
- Link transitions: Repeated up/down events can explain short interruptions.
- Negotiated speed and duplex: Unexpected values justify checking both ends of the link.
Counter names and meanings vary by vendor. Compare increases during the failure window, not lifetime totals alone. Follow a separate Ethernet link investigation when errors accompany link changes.
Next, compare upload and download utilization with available service capacity. An upload can fill a queue even when download use looks low. Check backup schedules, transfers, camera traffic, and gateway processor load.
Long polling intervals can hide brief bursts. Use finer monitoring where equipment supports it without excessive overhead. Avoid stress tests during active business operations. If authorized, pause one suspected workload briefly and compare results.
Package the Timeline for Escalation and Verify the Fix
Your packet loss timeline should connect measurements to business symptoms without overstating the cause. Summarize what failed, what remained healthy, and what changed during each event.
- Include timestamps, time zone, duration, and affected applications.
- Identify source devices, destinations, connection type, and VPN state.
- Attach raw probe logs and healthy-versus-failing path traces.
- Provide interface-counter differences and matching traffic graphs.
- List controlled comparisons, findings, and remaining uncertainties.
Share logs through an approved channel. Network traces can expose internal addresses and service details. Packet captures may contain sensitive traffic, so collect them only with authorization and a defined scope.
After a corrective change, repeat the original test through a comparable busy period. Confirm application recovery as well as cleaner probes. One quiet interval does not establish a lasting fix.
Professional remote assistance may help when several sites, provider paths, or managed devices need synchronized testing. Tech Rescue Ops LLC can help interpret the evidence and plan controlled checks without replacing diagnosis with disruptive guesswork.